NeurIPS 2026
SplitZip: Ultra-Fast Lossless KV Compression for Disaggregated LLM Serving
University of Notre Dame
Paper (arXiv 2605.01708) Code on GitHub
Abstract
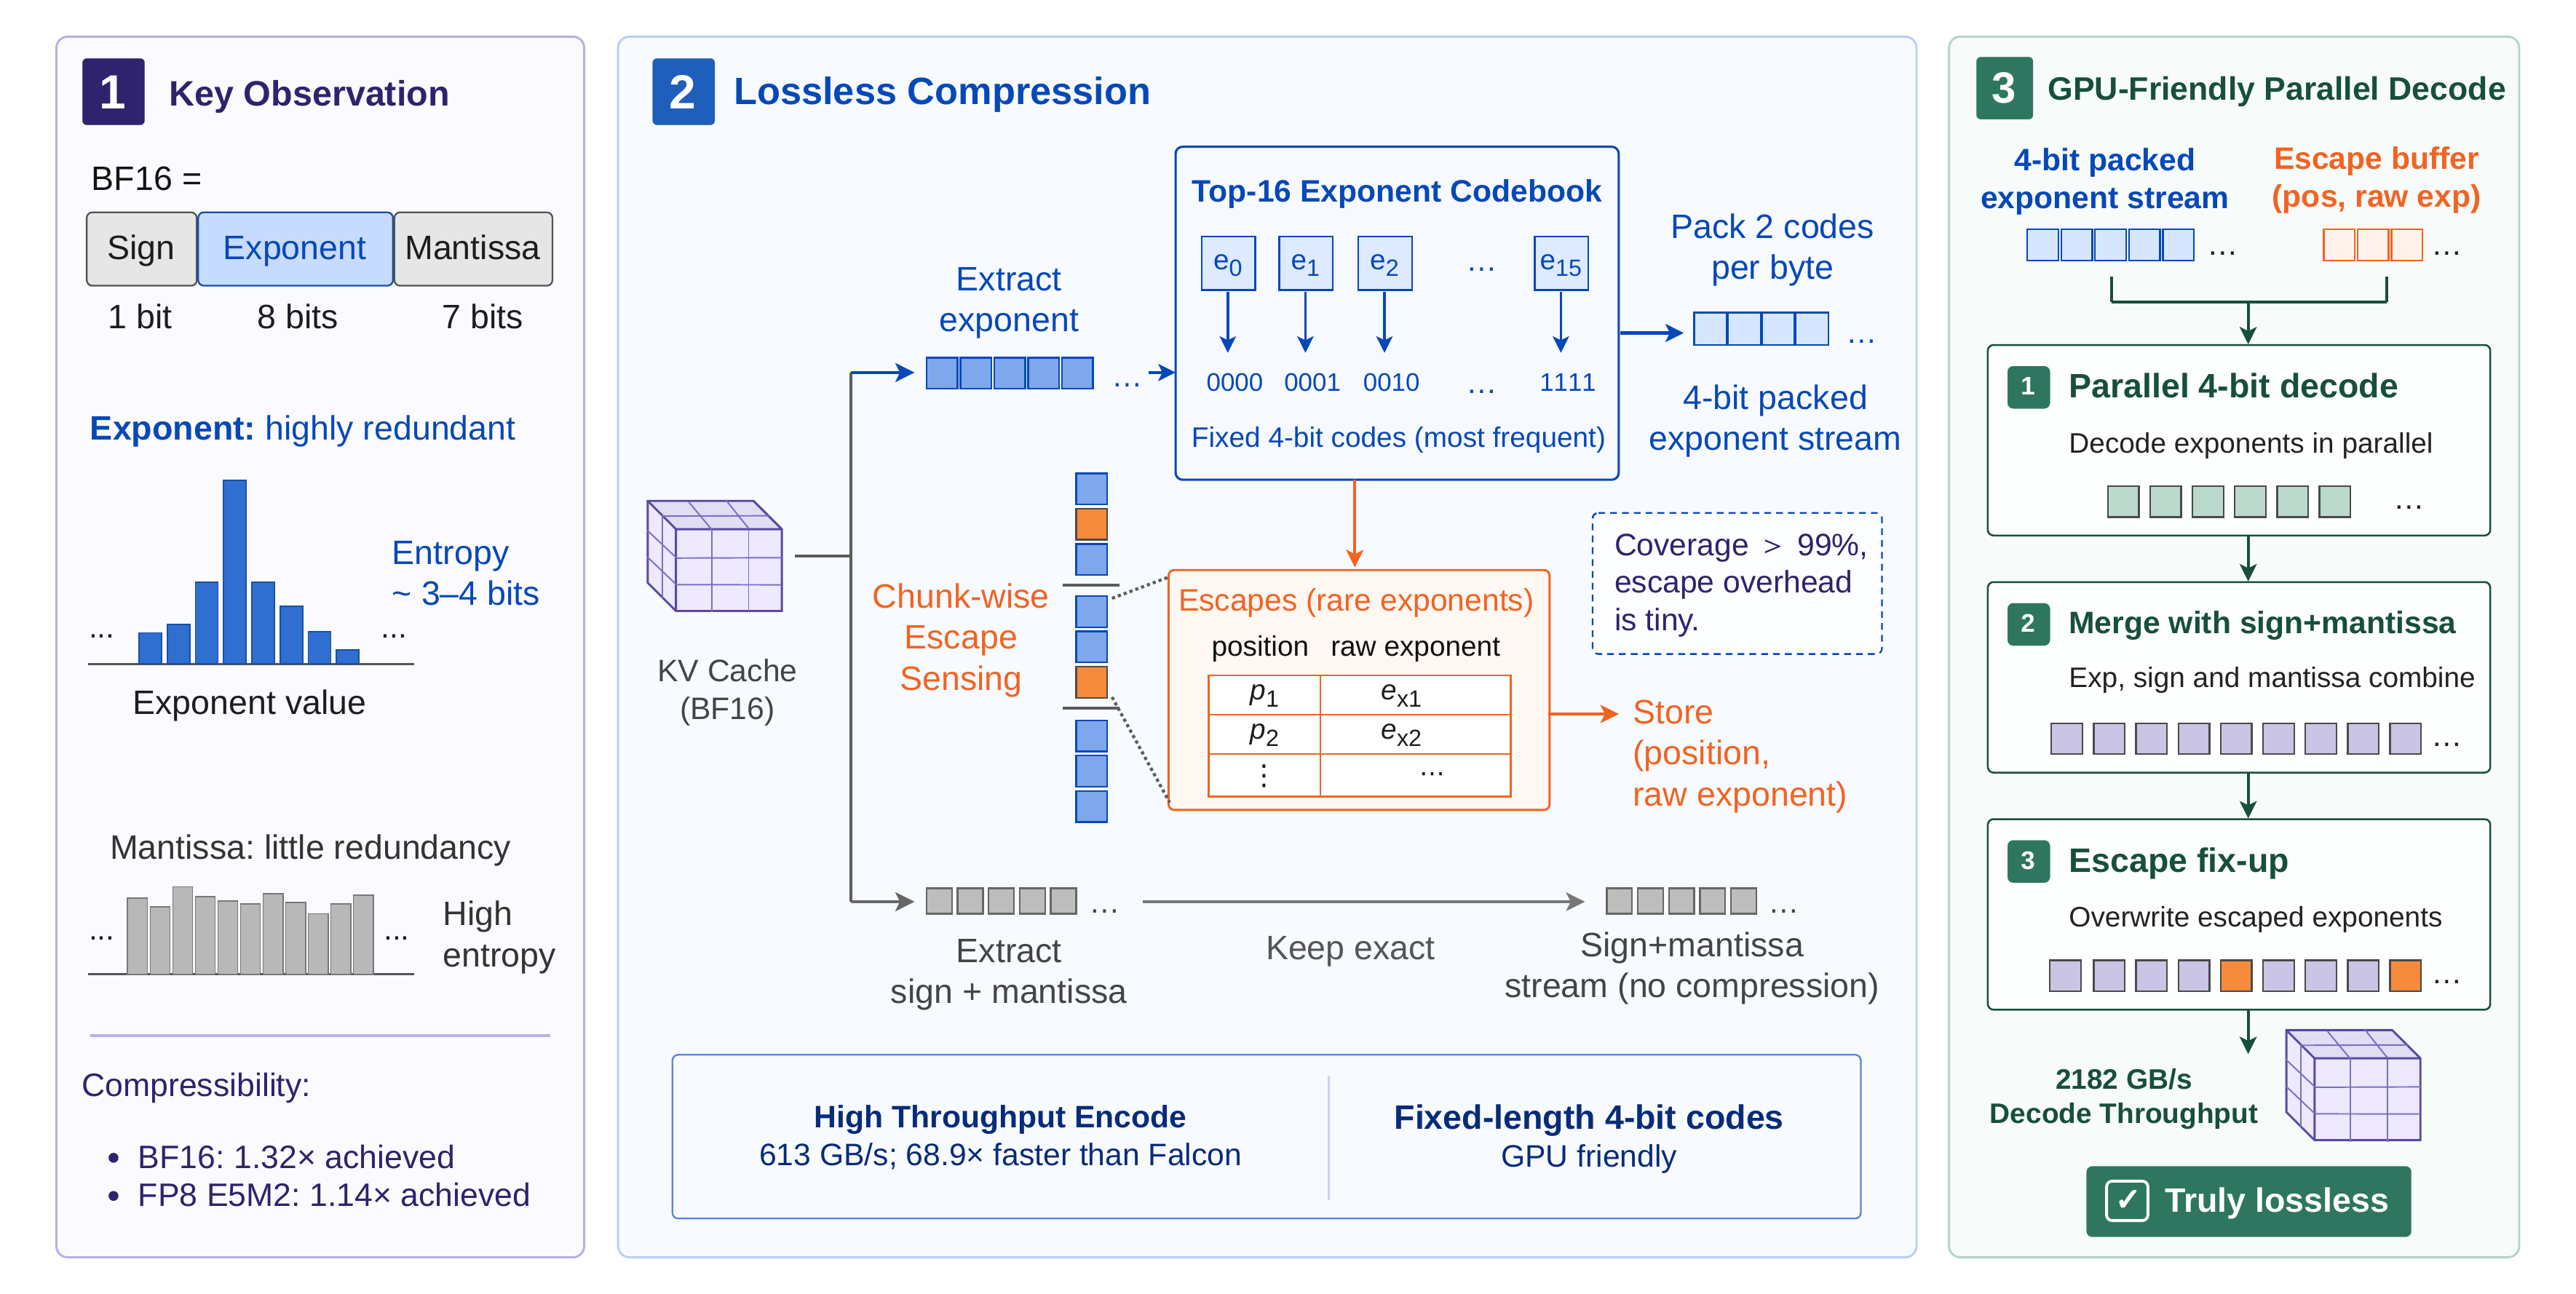
SplitZip is a GPU-friendly lossless compressor for KV cache transfer in prefill-decode disaggregated LLM serving. It preserves BF16 KV tensors bitwise while reducing transfer volume and keeping both compression and decompression on the latency-critical GPU path. The key observation is that BF16 KV activations have highly redundant exponent values. SplitZip encodes the most frequent exponent values with fixed 4-bit codes, keeps sign and mantissa bits exact, and routes rare exponent values through a sparse escape stream.
Key results
- 613.3 GB/sencode throughput (H200)
- 2181.8 GB/sdecode throughput
- 1.32×faster BF16 KV transfer
- 1.30×lower TTFT (128K context)
- 1.23×higher request throughput
- +1.14×extra compression on top of FP8 KV
Comparison
| Method | Encode (GB/s) | Decode (GB/s) |
|---|---|---|
| SplitZip | 613.3 | 2181.8 |
| nvCOMP Bitcomp | 341.5 | 147.7 |
| nvCOMP Cascaded | 111.8 | 155.2 |
| nvCOMP LZ4 | 13.4 | 137.1 |
| ZipServ (kernel) | – | 1260.9 |
| DFloat11 | 0.004 | 468.2 |
| Falcon | 8.9 | 14.4 |
| ZipNN | 1.2 | 1.7 |
FAQ
How can I reduce KV cache transfer time between prefill and decode nodes?
Send fewer bytes without changing any values. SplitZip compresses the BF16 KV cache on the prefill GPU and decompresses it on the decode GPU. Both steps run far faster than the network link, so the saved bytes turn directly into lower transfer time and time-to-first-token (TTFT).
Is SplitZip lossy?
No. Sign and mantissa bits are stored unchanged, and exponents are coded losslessly with a sparse escape path for rare values. Decoded KV tensors are bitwise identical to the originals.
Does it work with an FP8 KV cache?
Yes. Applied on top of an FP8 (E5M2) KV cache it gives up to 1.14× additional compression without further accuracy risk.
Which serving frameworks does it support?
SplitZip was evaluated in SGLang prefill–decode disaggregation with Mooncake as the KV transfer engine over RoCE (4×200G). The codec is a standalone PyTorch/Triton module.
How does it compare with nvCOMP, DFloat11 or ZipNN?
On real BF16 KV activations SplitZip encodes 1.8× faster than the fastest nvCOMP codec and decodes 14× faster. DFloat11, ZipNN and ZipServ target model weights and are too slow to encode KV on the fly.
Which models were tested?
Qwen3-32B, Qwen3-30B-A3B (MoE), Llama-3-8B and Phi-2.
Citation
@misc{guo2026splitzipultrafastlossless,
  title={SplitZip: Ultra Fast Lossless KV Compression for Disaggregated LLM Serving},
  author={Yipin Guo and Siddharth Joshi},
  year={2026},
  eprint={2605.01708},
  archivePrefix={arXiv},
  primaryClass={cs.DC},
  url={https://arxiv.org/abs/2605.01708},
}