2025 – 2030Anticipated
PhD · Computer Science & Engineering
University of Notre Dame — South Bend, IN
Advisor: Prof. Siddharth Joshi · Arthur J. Schmitt Leadership Fellowship · GPA 3.93 / 4.0
PhD Student · University of Notre Dame
I build efficient machine-learning systems — from tiny on-device networks to large language models — trading costly multiplications for shifts, adds, and low-bit computation.
Education
University of Notre Dame — South Bend, IN
Advisor: Prof. Siddharth Joshi · Arthur J. Schmitt Leadership Fellowship · GPA 3.93 / 4.0
Zhejiang University — Hangzhou, China
Advisor: Prof. Qinyuan Ren · Pattern Recognition & Intelligent Systems · GPA 91 / 100 · TOEFL 104
Zhejiang University — Hangzhou, China
GPA 3.88 / 4.0 (last two years 3.93) · Second Prize Scholarship · Excellent Academic Award
Experience
Prof. Zhijian Liu · Lucas Liebenwein
Accelerated Gemma-4B generation to 250 tokens/s on DGX Spark; contributing to the training and deployment of vision-language models (VLMs).
Prof. Yingyan (Celine) Lin · Dr. Haoran You
Efficient transformers and multiplication-less LLMs — ShiftAddViT (NeurIPS'23) and ShiftAddLLM (NeurIPS'24).
Hangzhou, China
IoT device testing; built automation scripts and validated AI functionality.
Selected Work
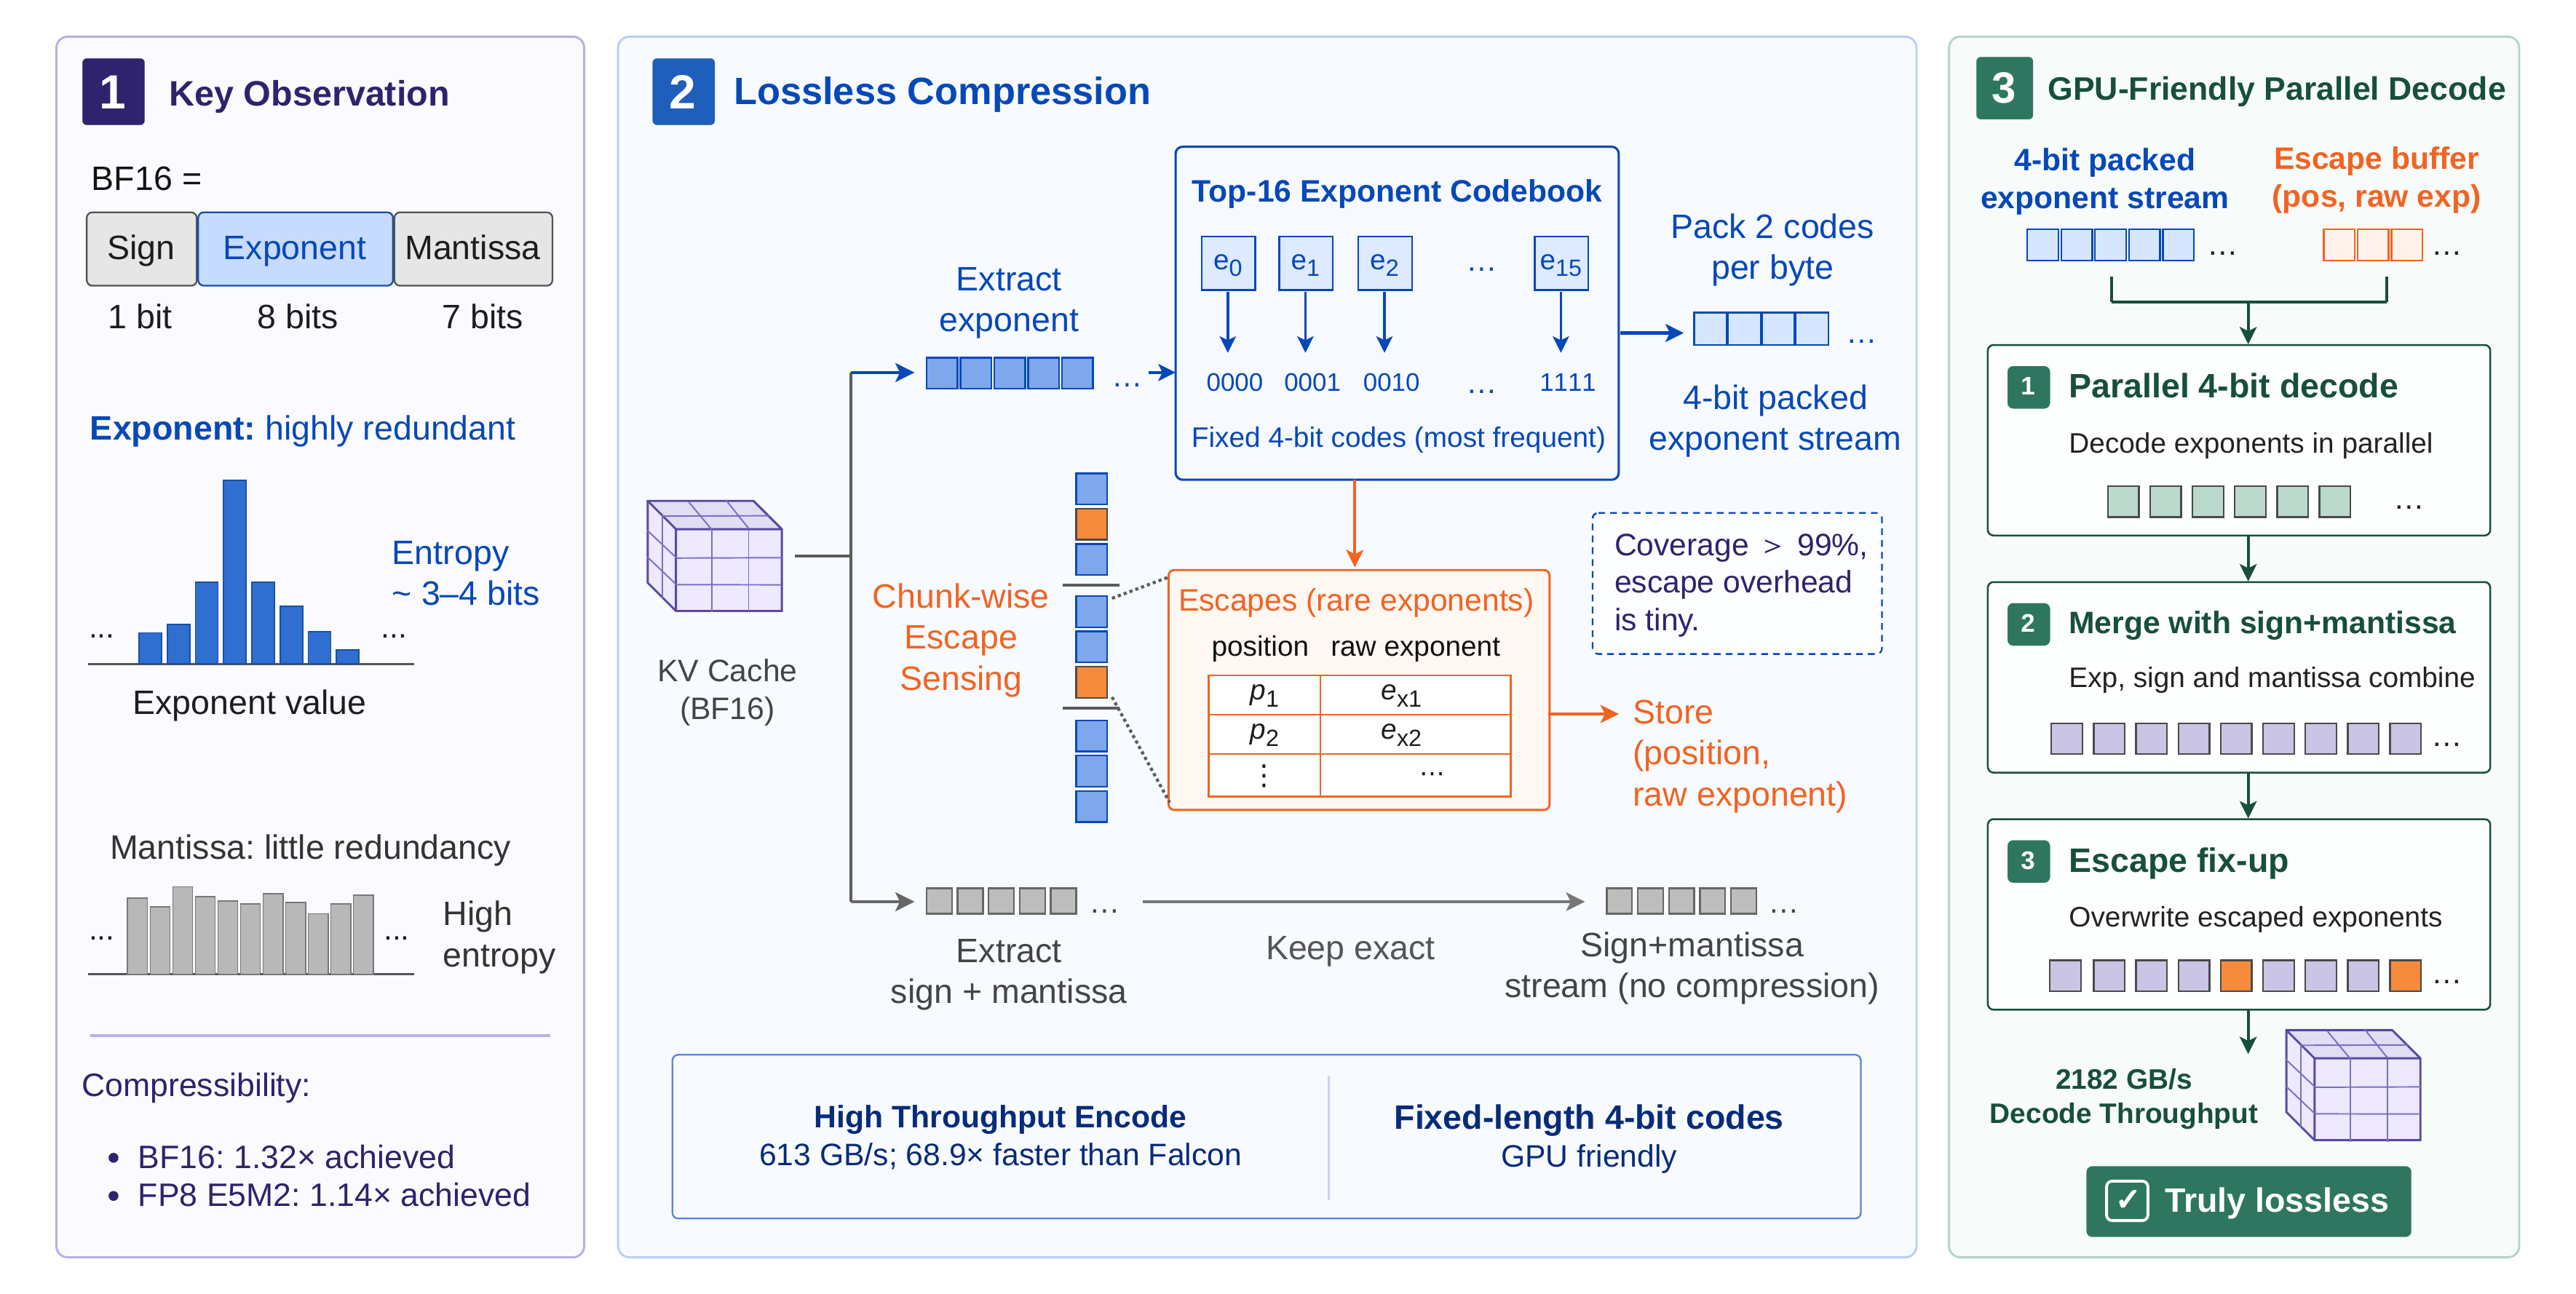
Ultra-high-throughput, truly lossless KV-cache compression for disaggregated LLM serving — encoding high-frequency BF16 exponent values with fixed-length 4-bit codes for GPU-friendly parallel decode.
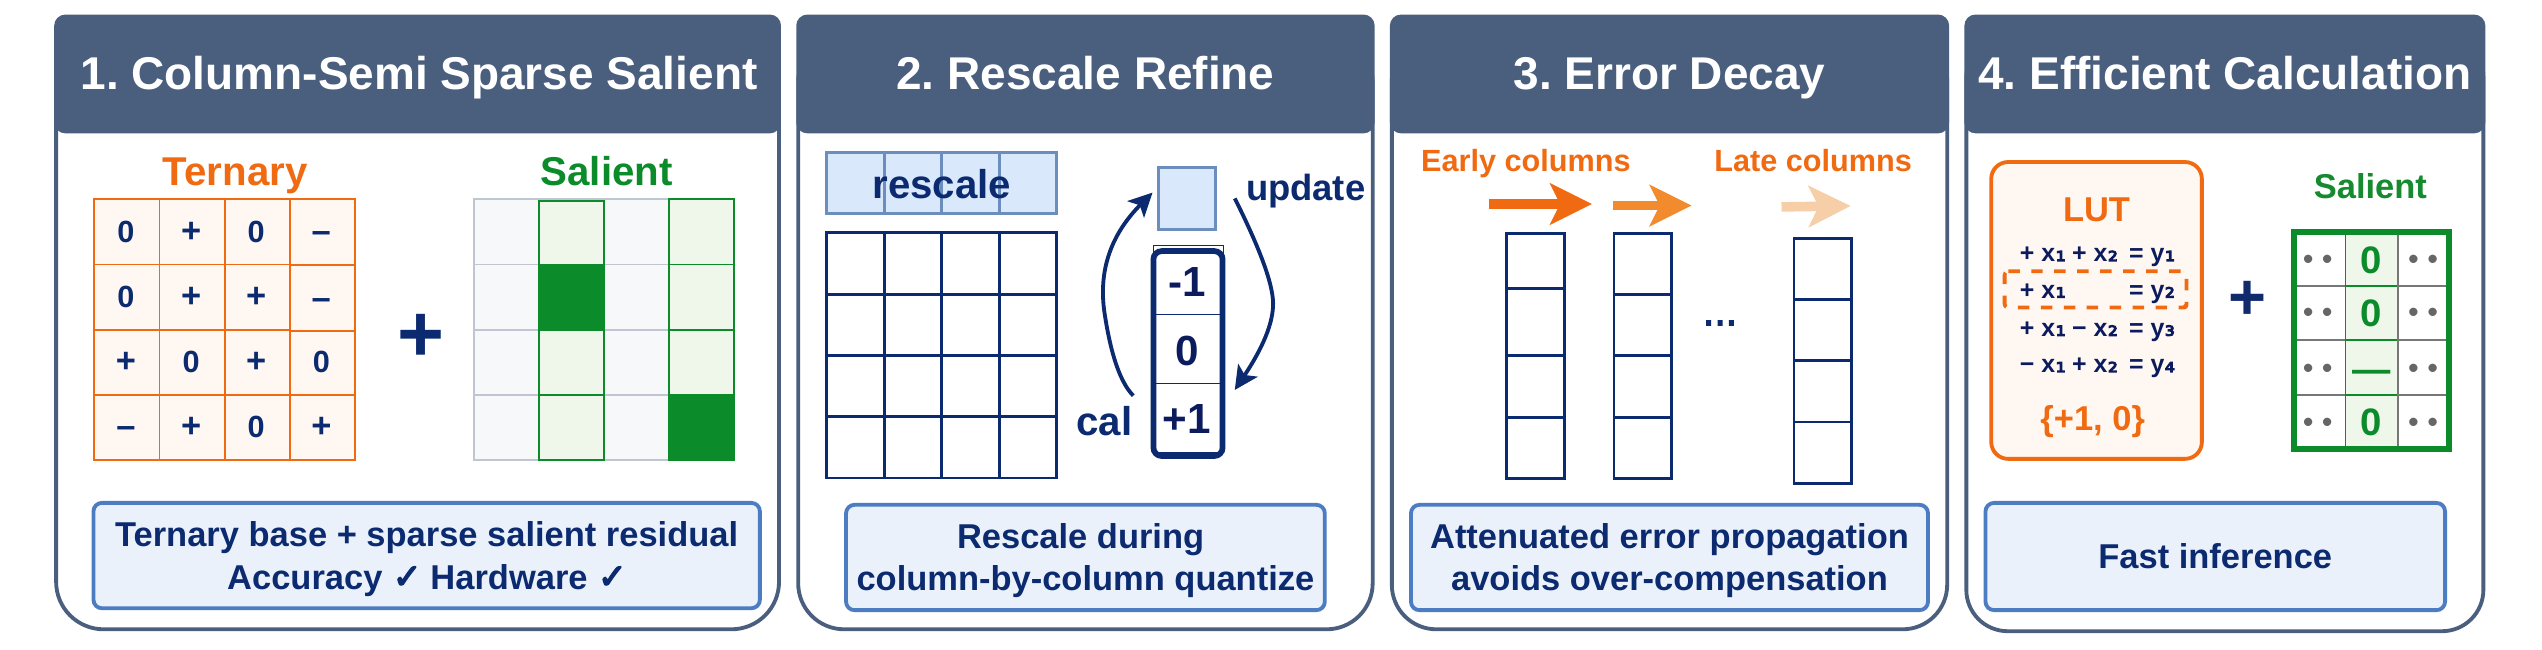
A ternary base plus a sparse residual for salient weights, refined column-by-column with attenuated error propagation — delivering accurate, hardware-friendly LLM inference via LUT-based computation.
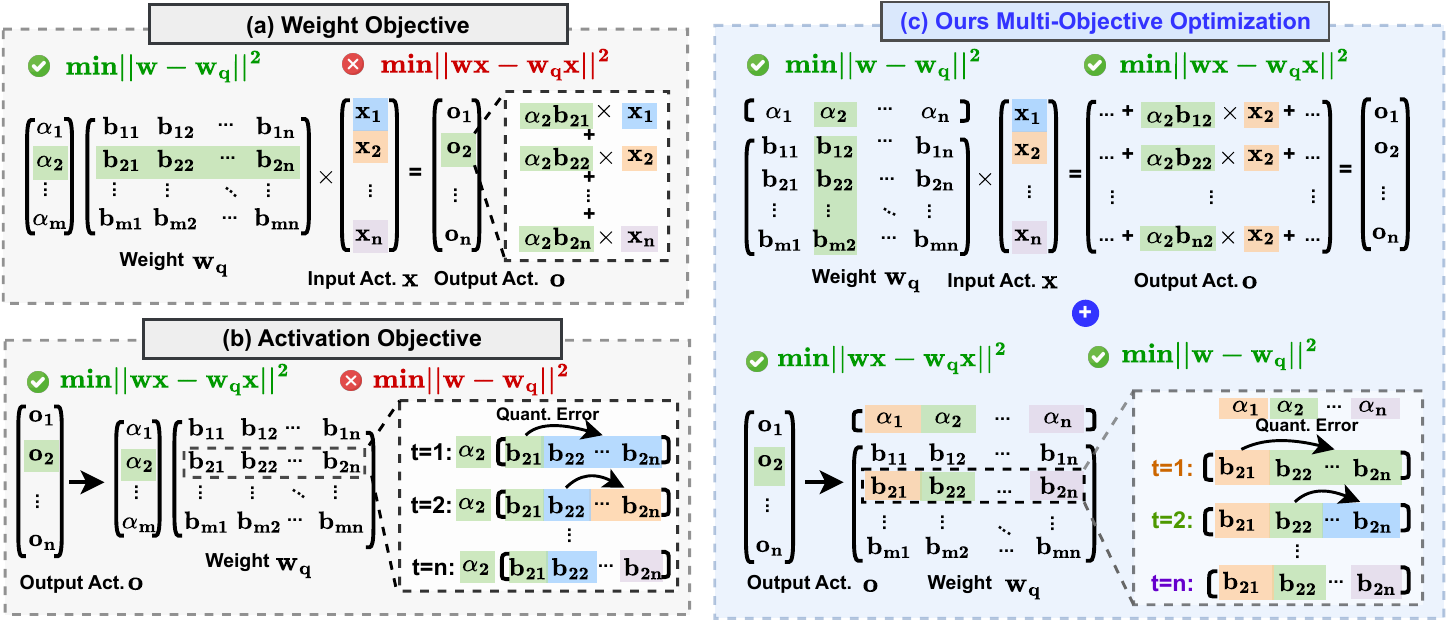
Accelerates pretrained LLMs via a post-training bitwise shift-and-add reparameterization, jointly optimizing weight and output-activation objectives. Introduces a mixed, automated bit-allocation strategy.
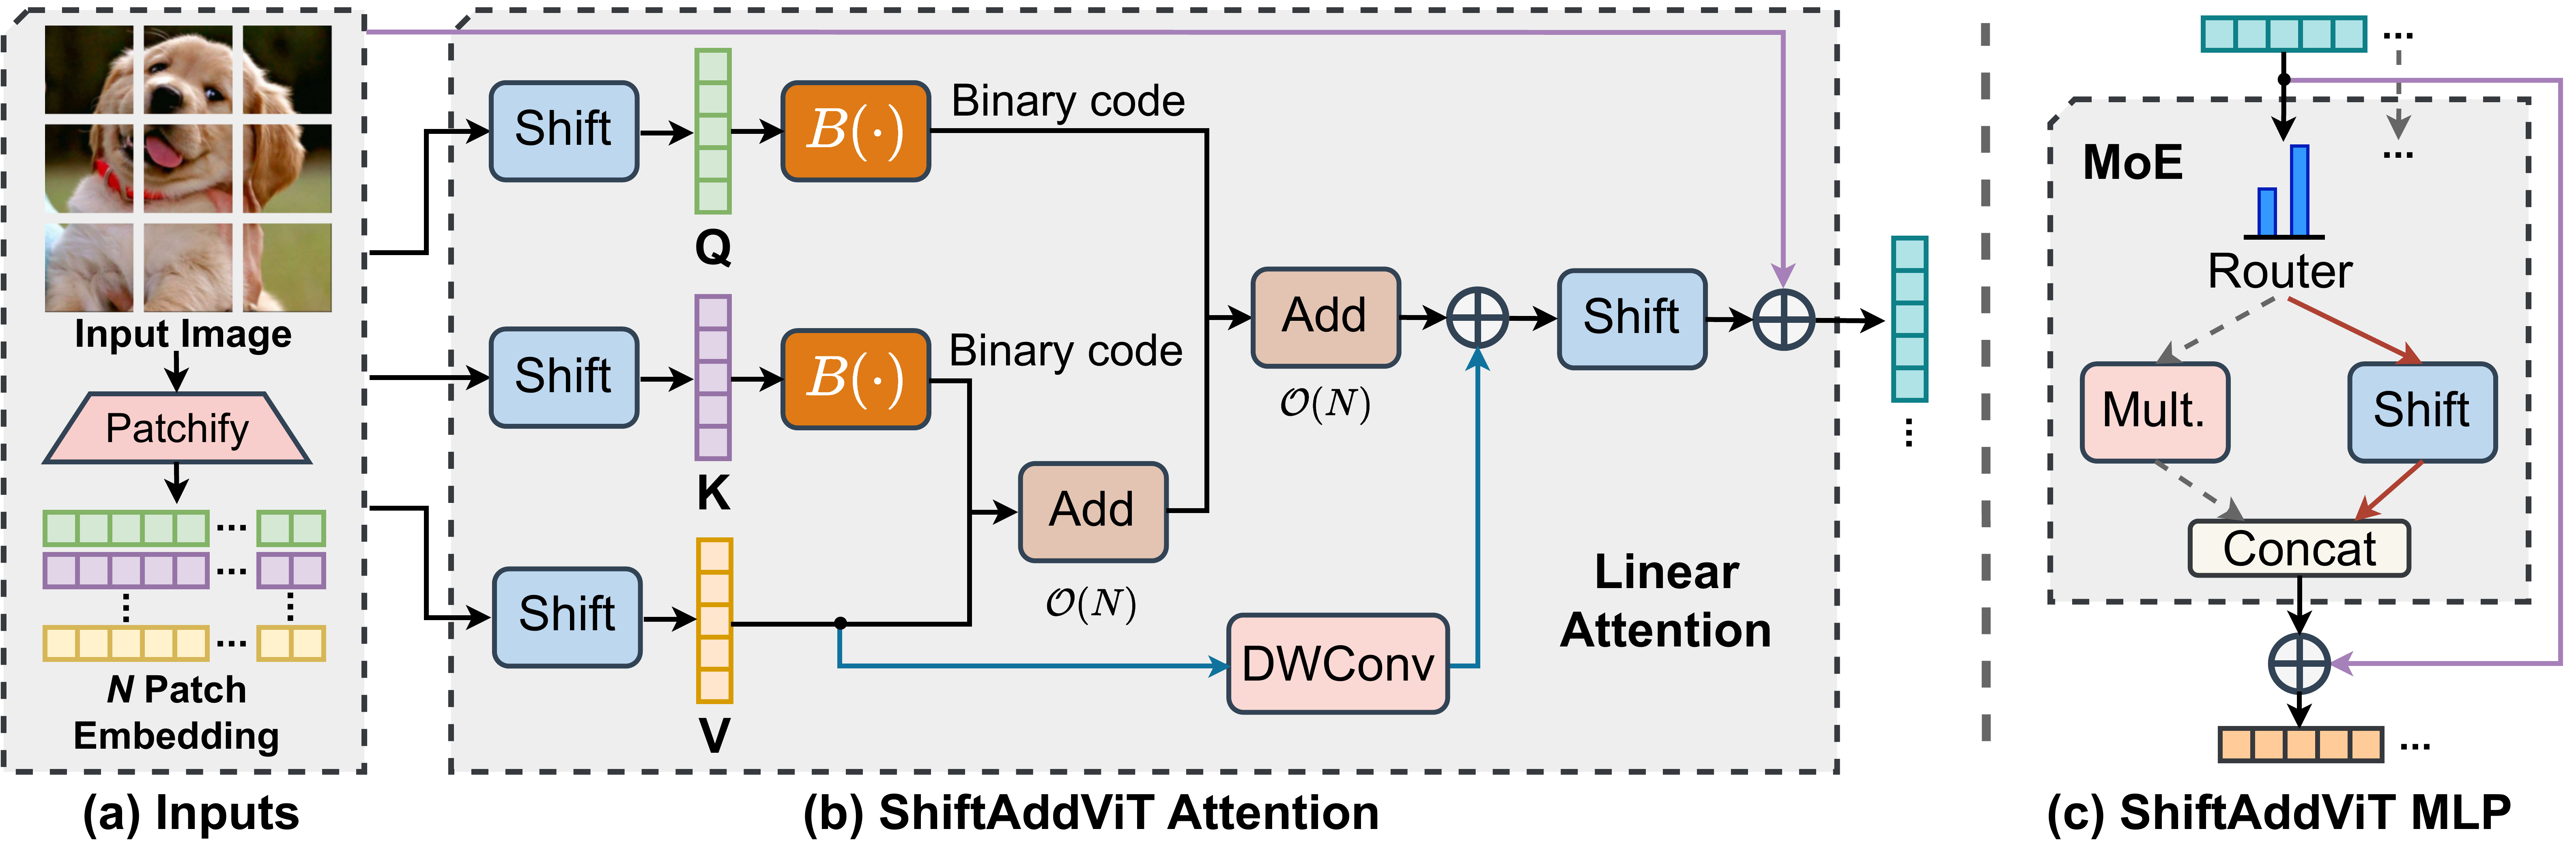
A linear additive-only attention paired with a mixture-of-experts that routes vital tokens through multiplications and less-crucial ones through shifts — cutting cost while preserving ViT accuracy.
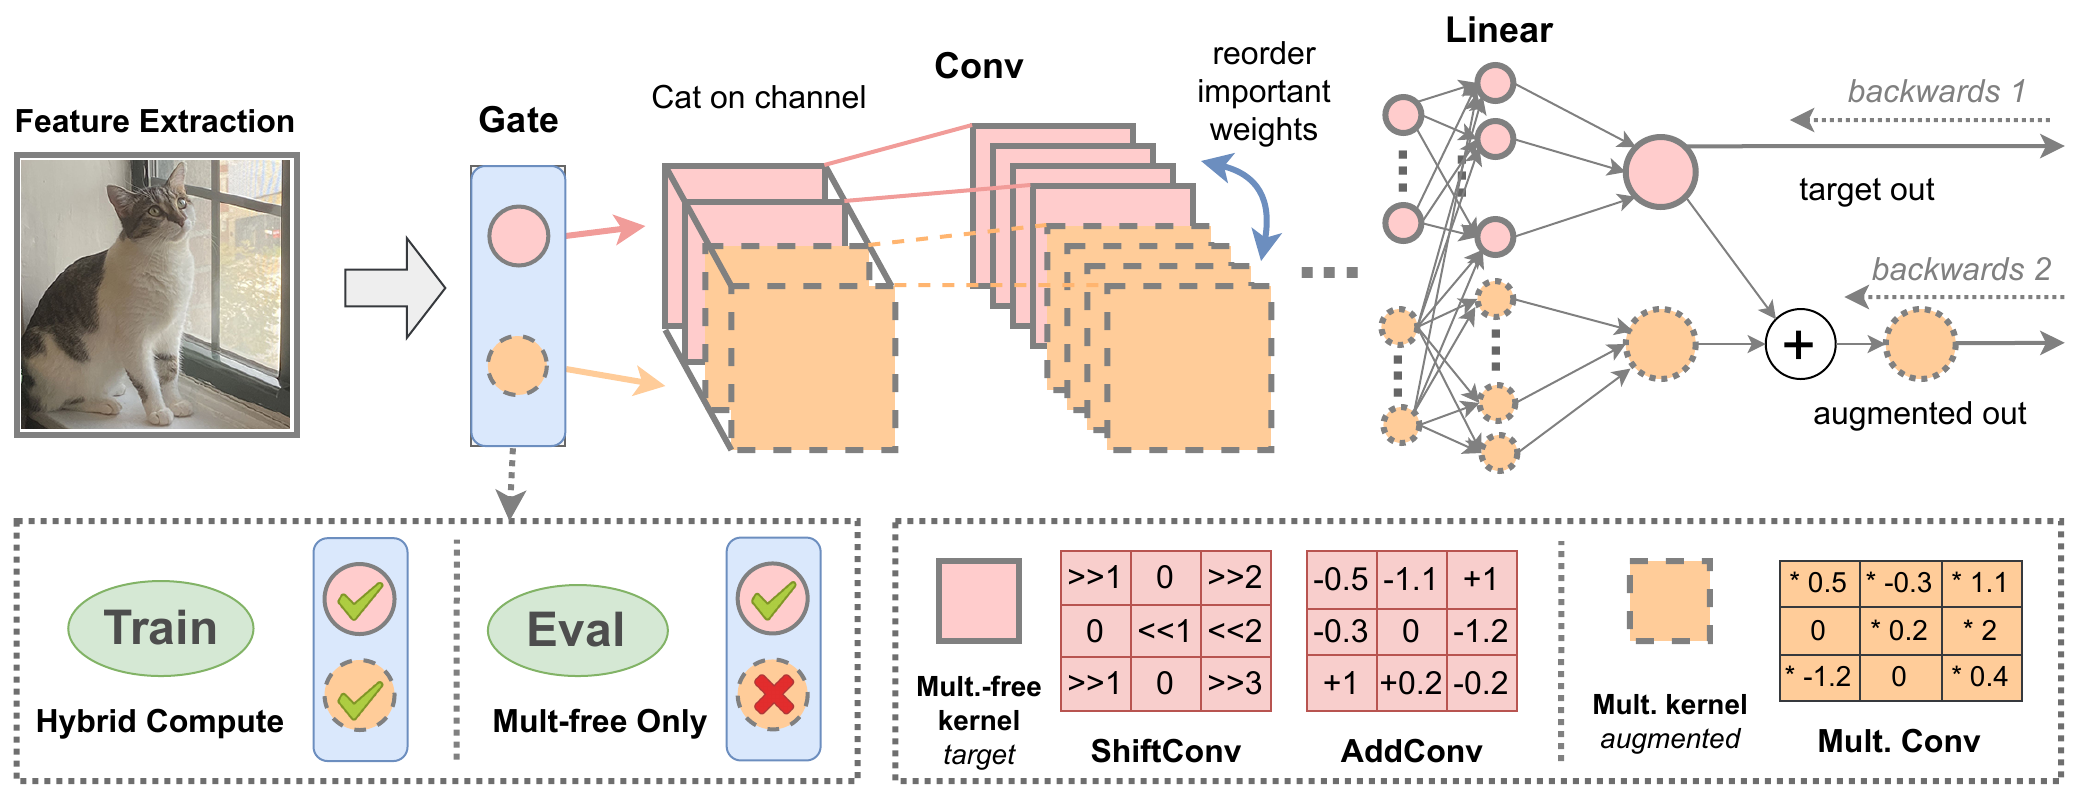
Uses multiplication to augment ShiftAdd tiny neural networks during training only. The result beats multiplication-based counterparts with zero added inference overhead.
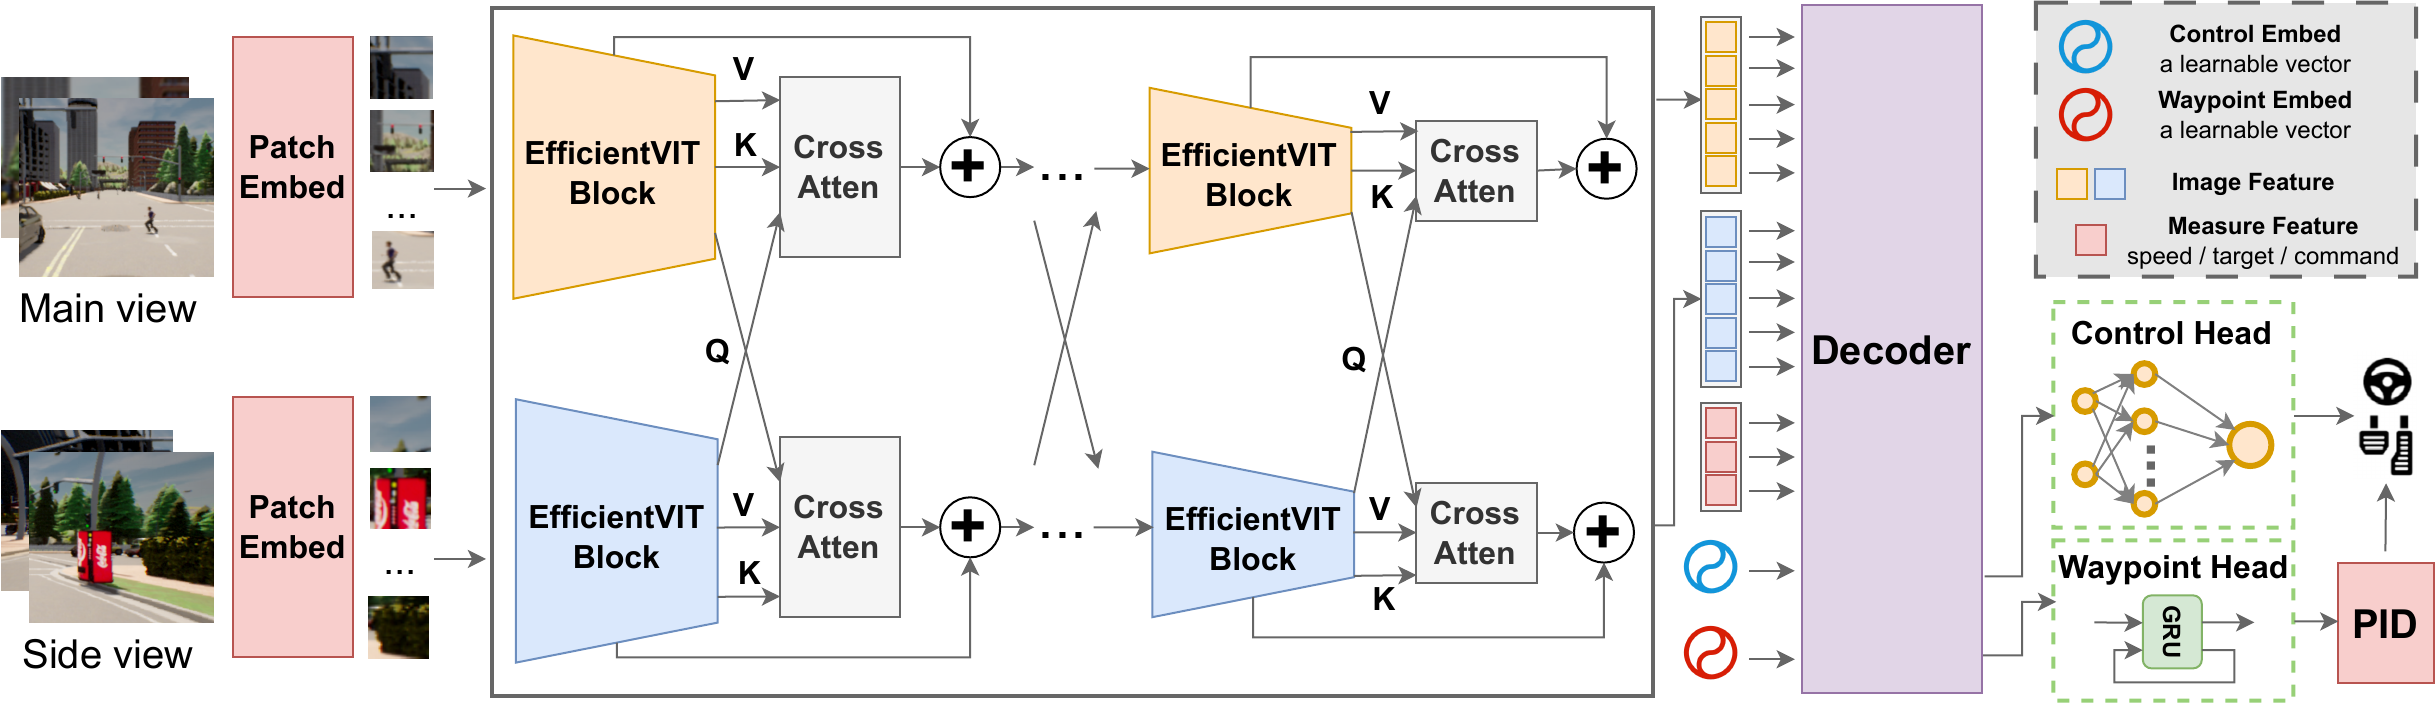
A lightweight Transformer-based end-to-end autonomous-driving network. Uses 37.6% of the parameters and 8.7% of the compute with only a 0.4% lower driving score.
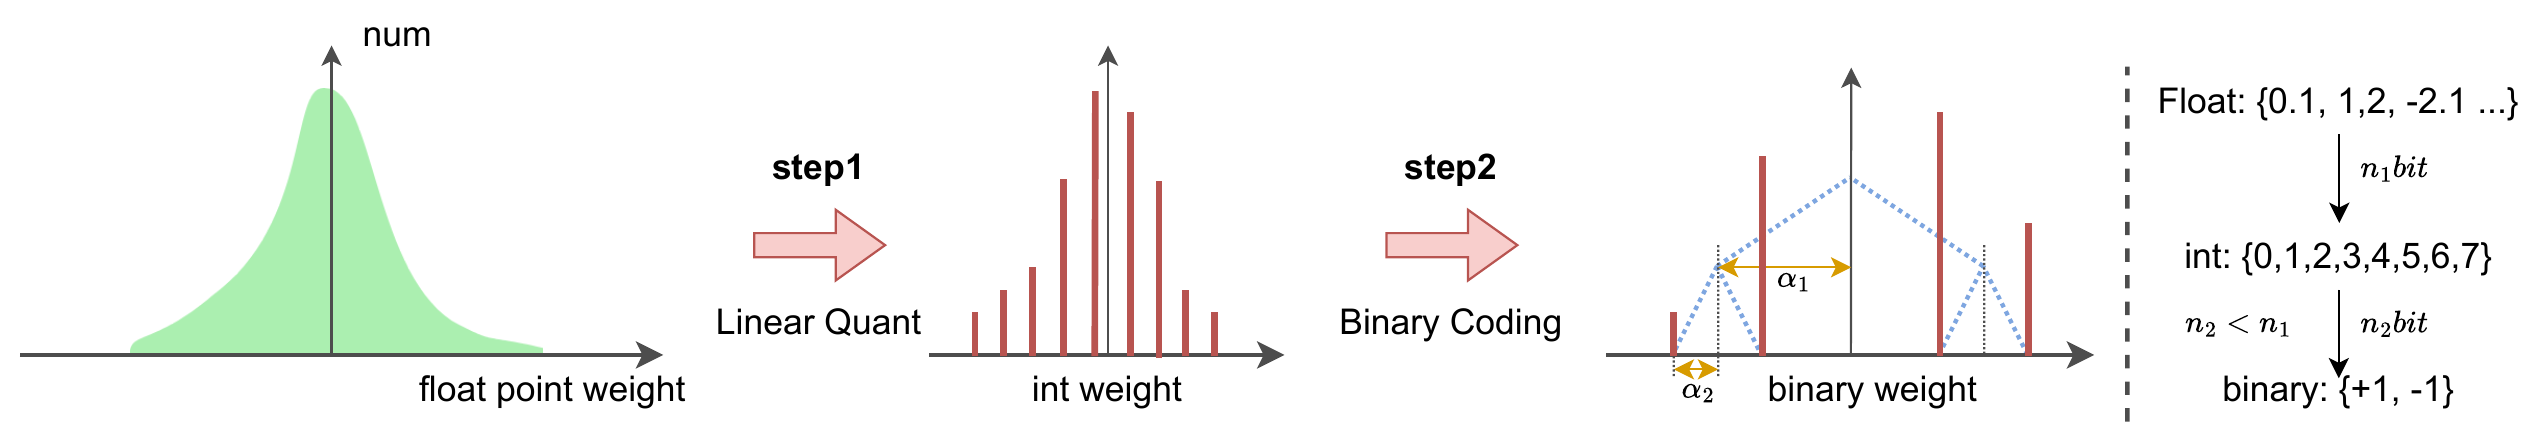
Motivated by the insight that GPTQ overfits during quantization, GPTQT quantizes in two steps — first to relatively high bits, then to low-bit binary coding — for stronger low-bit LLMs.
Projects
Controller-circuit design; MCU software on STM32 and Linux software-architecture design for an autonomous handling robot.
Bachelor's final-year project — safer AEB strategies for intelligent vehicles, validated in MATLAB simulation.
Deployment of a quantized neural network onto a resource-constrained MCU for the ACM/IEEE TinyML Design Contest.
PythonPyTorchC / C++MATLABAssemblyJavaScript Altium DesignerLCEDASolidWorks3D PrintingLaser Cutting